
Hybrid Storage Engine
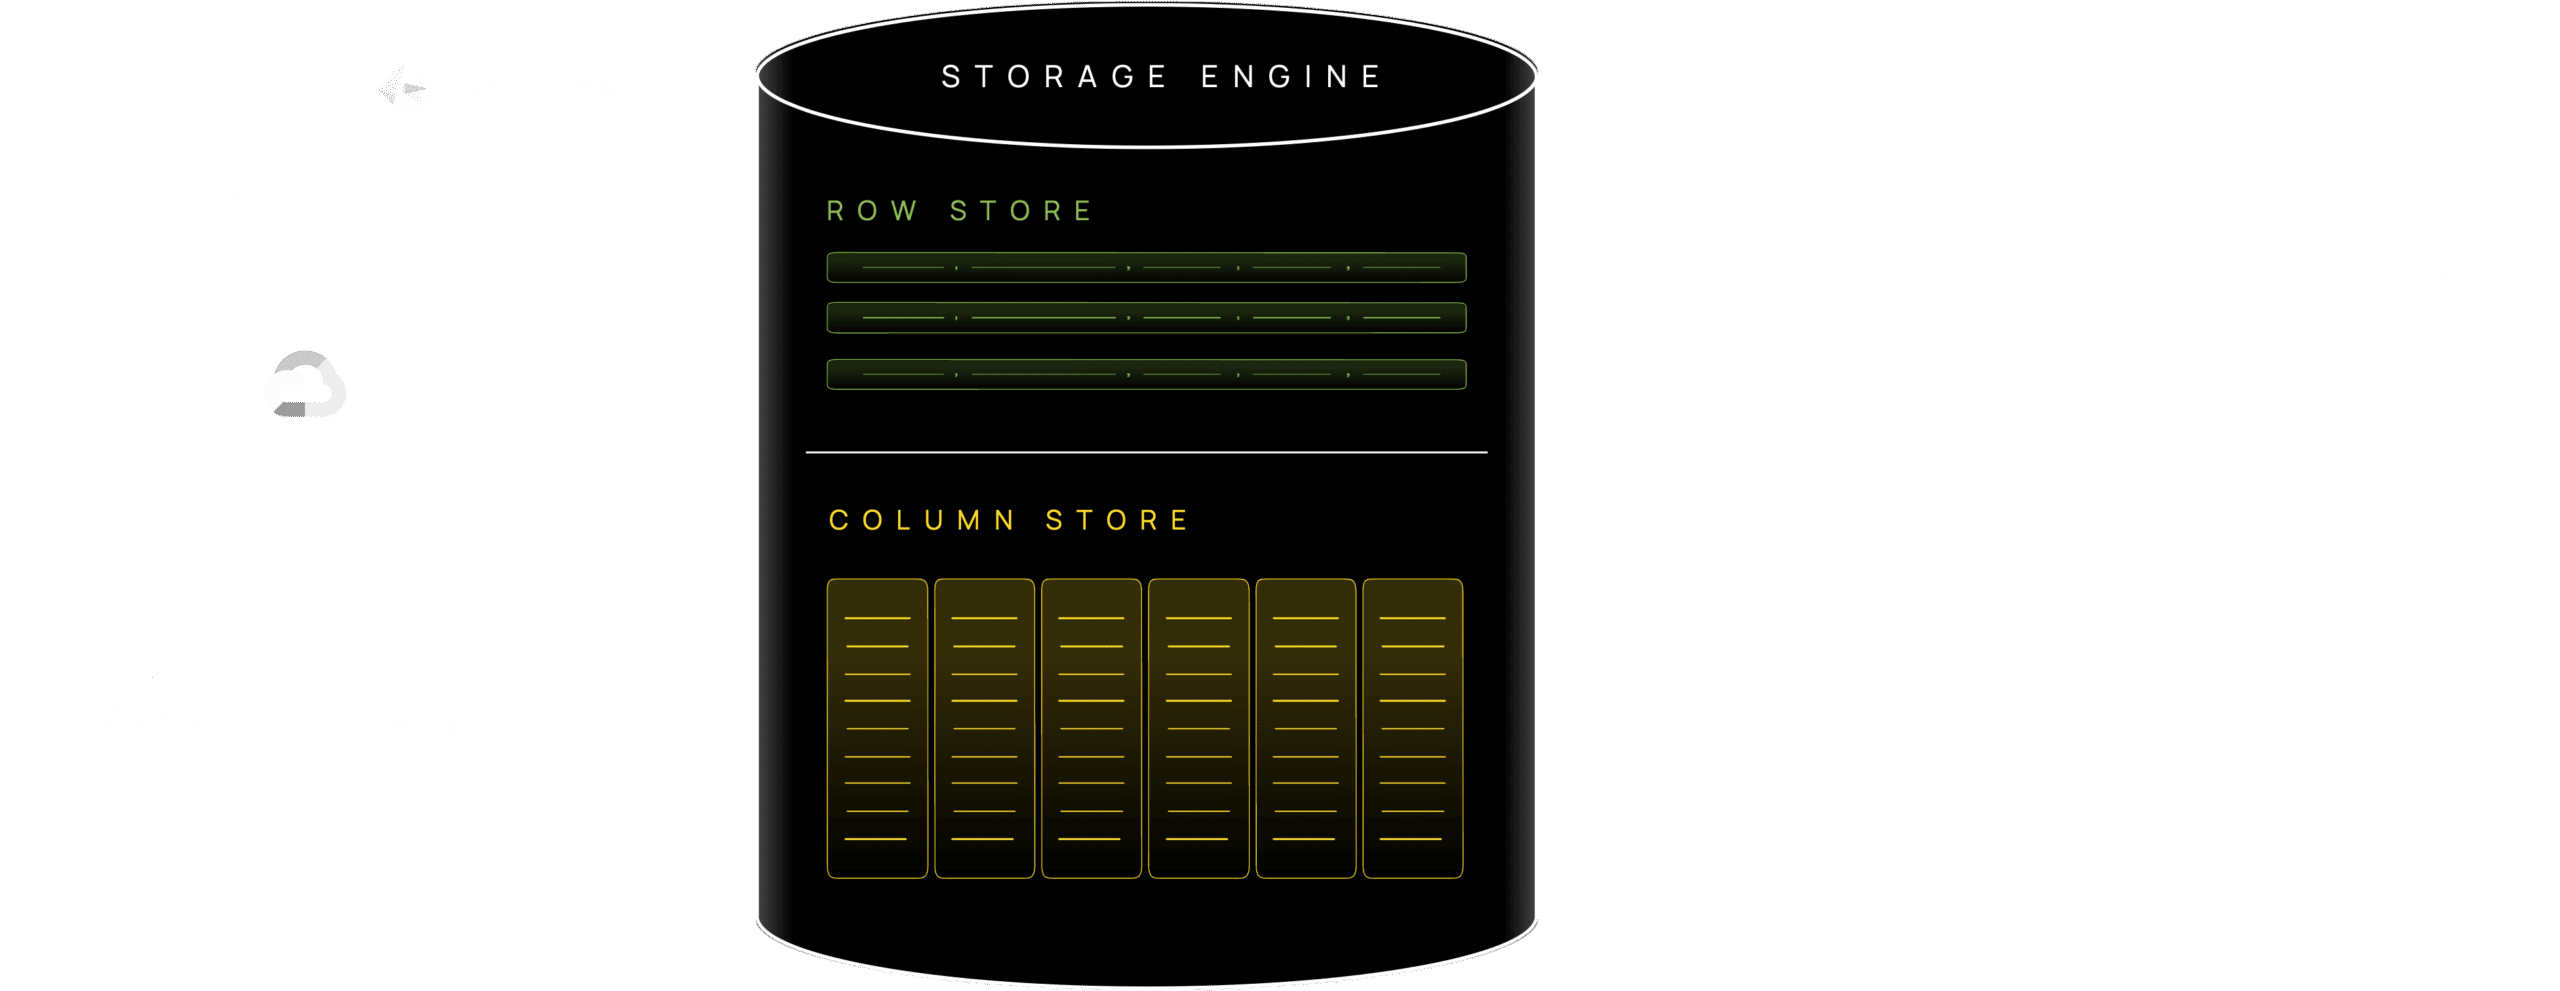
Row- and column-oriented storage combine to support both high frequency small inserts and large bulk loads with consistent transactional semantics.
Yellowbrick is uniquely capable of supporting highly concurrent, ad-hoc query workloads along with continual data ingest. Our product can ingest real-time data with the latency of OLTP databases while supporting columnar queries across huge data sets, without pauses for data reorganization, unpredictable spikes in query runtimes, or ongoing data vacuuming.
Row- and column-oriented storage combine to support both high frequency small inserts and large bulk loads with consistent transactional semantics.

With MVCC, loads, writes and updates never block queries, and multiple loads can run concurrently.

Isolate ELT processes to separate compute clusters so they have zero impact on other users. Prioritize important queries and guarantee resource availability to meet business SLAs even under periods of high load.

Statistics are automatically kept up to date and efficiently incrementally updated. No secondary indexes. No data vacuuming required.

Committed data is available immediately to query across multiple elastic compute clusters.

Connectors to Kafka and Spark, AirByte, AWS Data Migration Service, Oracle GoldenGate, Fivetran, Informatica, and all your favorite data movement tools.

Use standard PostgreSQL ODBC, JDBC, and ADO.NET drivers with SQL INSERT and PostgreSQL \COPY commands. A Java bulk load SDK is also available.
AI and analytics are core to Ushur CXA. The promise of improved, expedited, and cost-efficient data analysis translates to better outcomes for our clients, which drives platform adoption. CXA thrives on a high-performance and dependable engine, and we were genuinely impressed by Yellowbrick Data’s ability to deliver this capability at a price point that perfectly aligns with our ambitious goals


