Outgrowing Redshift?
We can help.
Efficient scaling
Predictable Performance
Real-time Analytics
Trusted by Leading Enterprises
5X faster cube build performance
50% Reduction in DevOps Overhead
4.5x faster queries and 300% lower TCO
Redshift's challenges

Yellowbrick’s strengths
What our customers say
insightsoftware Accelerates Analytics Services with Yellowbrick
"Yellowbrick outperformed Redshift in every metric—4.5x faster queries and 300% lower TCO."
Problem
Insightsoftware struggled with inconsistent query performance and high costs associated with Redshift, especially as they scaled their services and customer base.
Solution
Yellowbrick provided predictable and consistent query performance, significantly reduced TCO, enabled faster customer onboarding -- without the need for additional instances.
Results
Insightsoftware saw up to 4.5x faster queries and 300% lower TCO after migrating to Yellowbrick, enabling them to accelerate their data analytics services and scale efficiently.
Solution Briefs
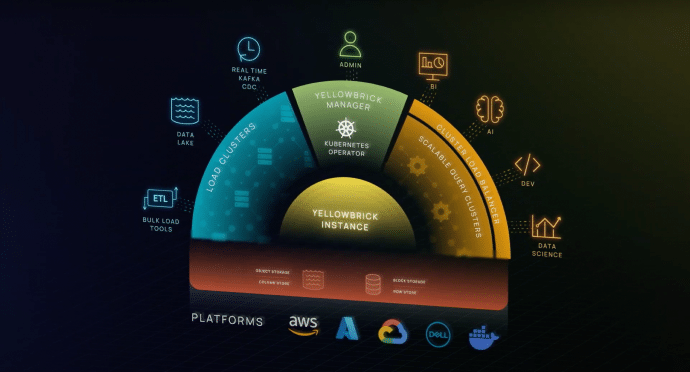
Load and Query Concurrently
Run analytics and data engineering together without conflict or complex orchestration.
Learn More about Load and Query Concurrently
Streaming Ingestion
Stream, ETL, and query in the same database. Avoid multiple solutions.
Learn More about Streaming Ingestion
Keep Data Local
Have absolute confidence in where data is located and processed.
Learn More about Keep Data Local
Elastic Scale
Handle unlimited concurrency, multi-tenancy, AI complexity or massive volumes.
Learn More about Elastic ScaleTrusted Migration Process
Dedicated Yellowbrick Customer Success Team
-

Step 1:
Information Transfer & AssessmentObjective: Gather necessary information and evaluate the customer’s environment.
Action: Transfer details from the account team and validate workflow, architecture, and data sources (ETL, BI tools).
Outcome: A complete understanding of the customer’s environment and migration components.
-

Step 2:
Build Migration InventoryObjective: Identify all components involved in the data migration process.
Action: Compile an inventory of objects, views, schemas, stored procedures, tables, roles, UDFs, etc.
Outcome: A comprehensive list of components required for migration.
-

Step 3:
Define Migration Path & Success CriteriaObjective: Establish the migration approach and define success metrics.
Action: Choose between Lift & Shift, object mapping, or code refactoring, and agree on functionality and performance targets.
Outcome: A clear migration strategy and defined success criteria.
-

Step 4:
Plan, Execute & Validate MigrationObjective: Plan, perform, and validate the migration, ensuring data integrity and performance standards.
Action: Assign tasks, run Yellowbrick in parallel, and validate data consistency and performance under all conditions.
Outcome: Migration is executed, with successful data validation and performance targets met.
Transform data into action
Ready to Get started?